Tool Verdicts
Verdicts on the tools touching your data. What changed, what it costs, who owns the toggle.
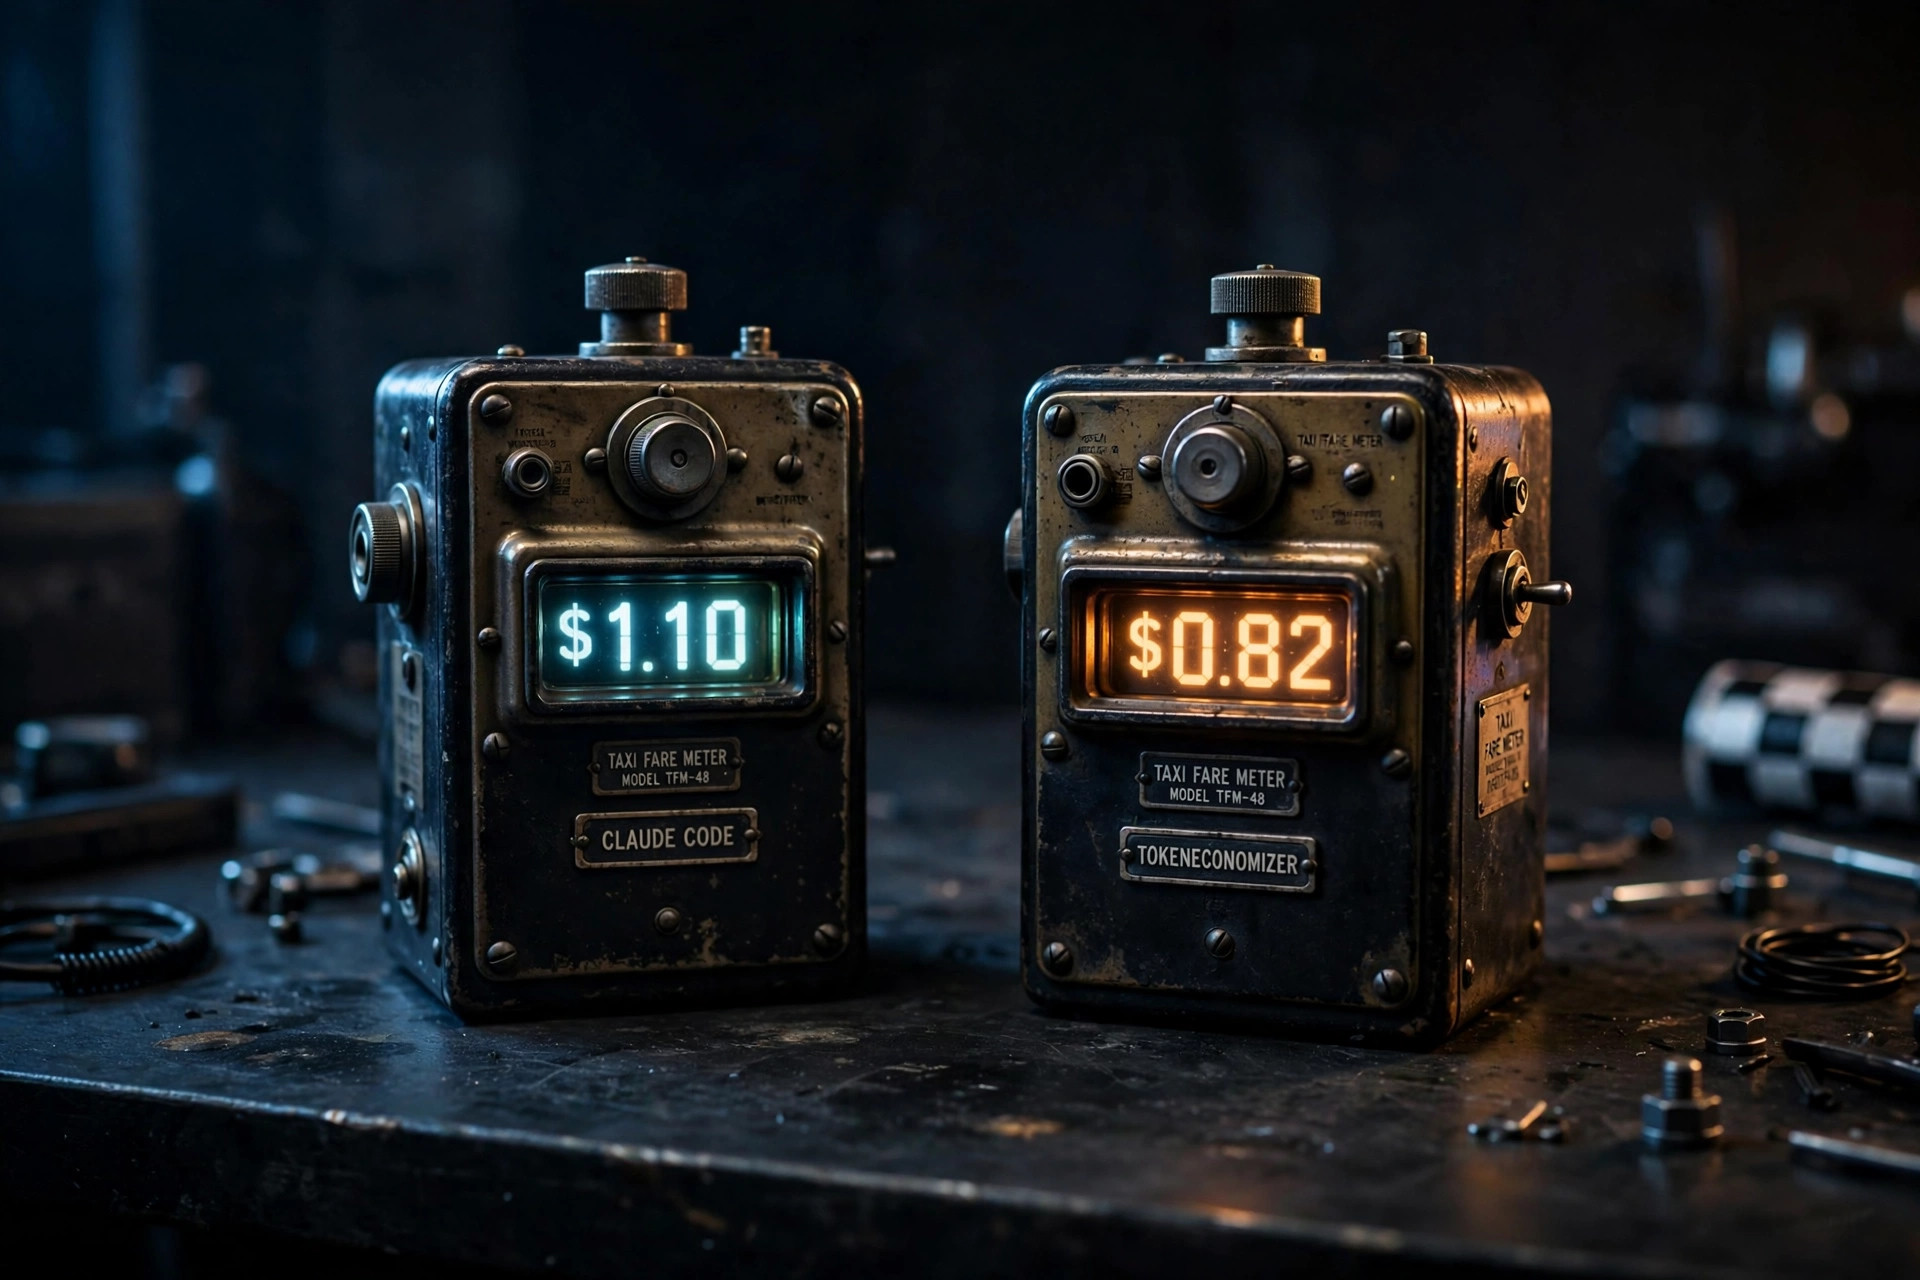
TokenEconomizer vs Claude Code: Same 9 Tasks, $1.10 vs $0.82
Nine Web-Bench tasks, same setup both sides. Plain Claude Code cost $1.10. With Microsoft's TokenEconomizer plugin, $0.82, 25 percent less, same 9/9 solved. The split starts at task 4, when the plugin's tool-masking rule can first bite.
Hydrogen Tied Fable at 51%: 82 Cents vs $4.64 (AutomationBench)
On Zapier's AutomationBench, Gemini 4 Hydrogen tied Claude Fable 5.2 at 51 percent, 82 cents a task versus $4.64. Same score, 5.7 times the cost. Budget the finished-task number, not the token rate.
RAGFlow 1.0 Claims 100x the Concurrency
RAGFlow 1.0 shipped November 6, rewritten in Go, repositioned as an agent native database. The vendor's claim is 100x the concurrency and 90 percent token savings on a hit. The real question is whether the agent uses the compiled context at all.
Four always-on AI agents in ten weeks: Grok Bot, Muse, dots, Claude Duet
Four companies announced an always-on AI agent in about ten weeks. Here is what each one is, on the facts, and the question a data engineer should ask before handing one production access.
Neo4j Context Engine: Your Agent Sounds Sure. It Is Guessing.
Neo4j launched a Context Engine for AI agents on October 20. The pitch: agents are a third consumer of data, and they do not know what customer, account, or risk means inside your company. The fix is a six-layer ontology. The catch is the mapping work it does not remove.
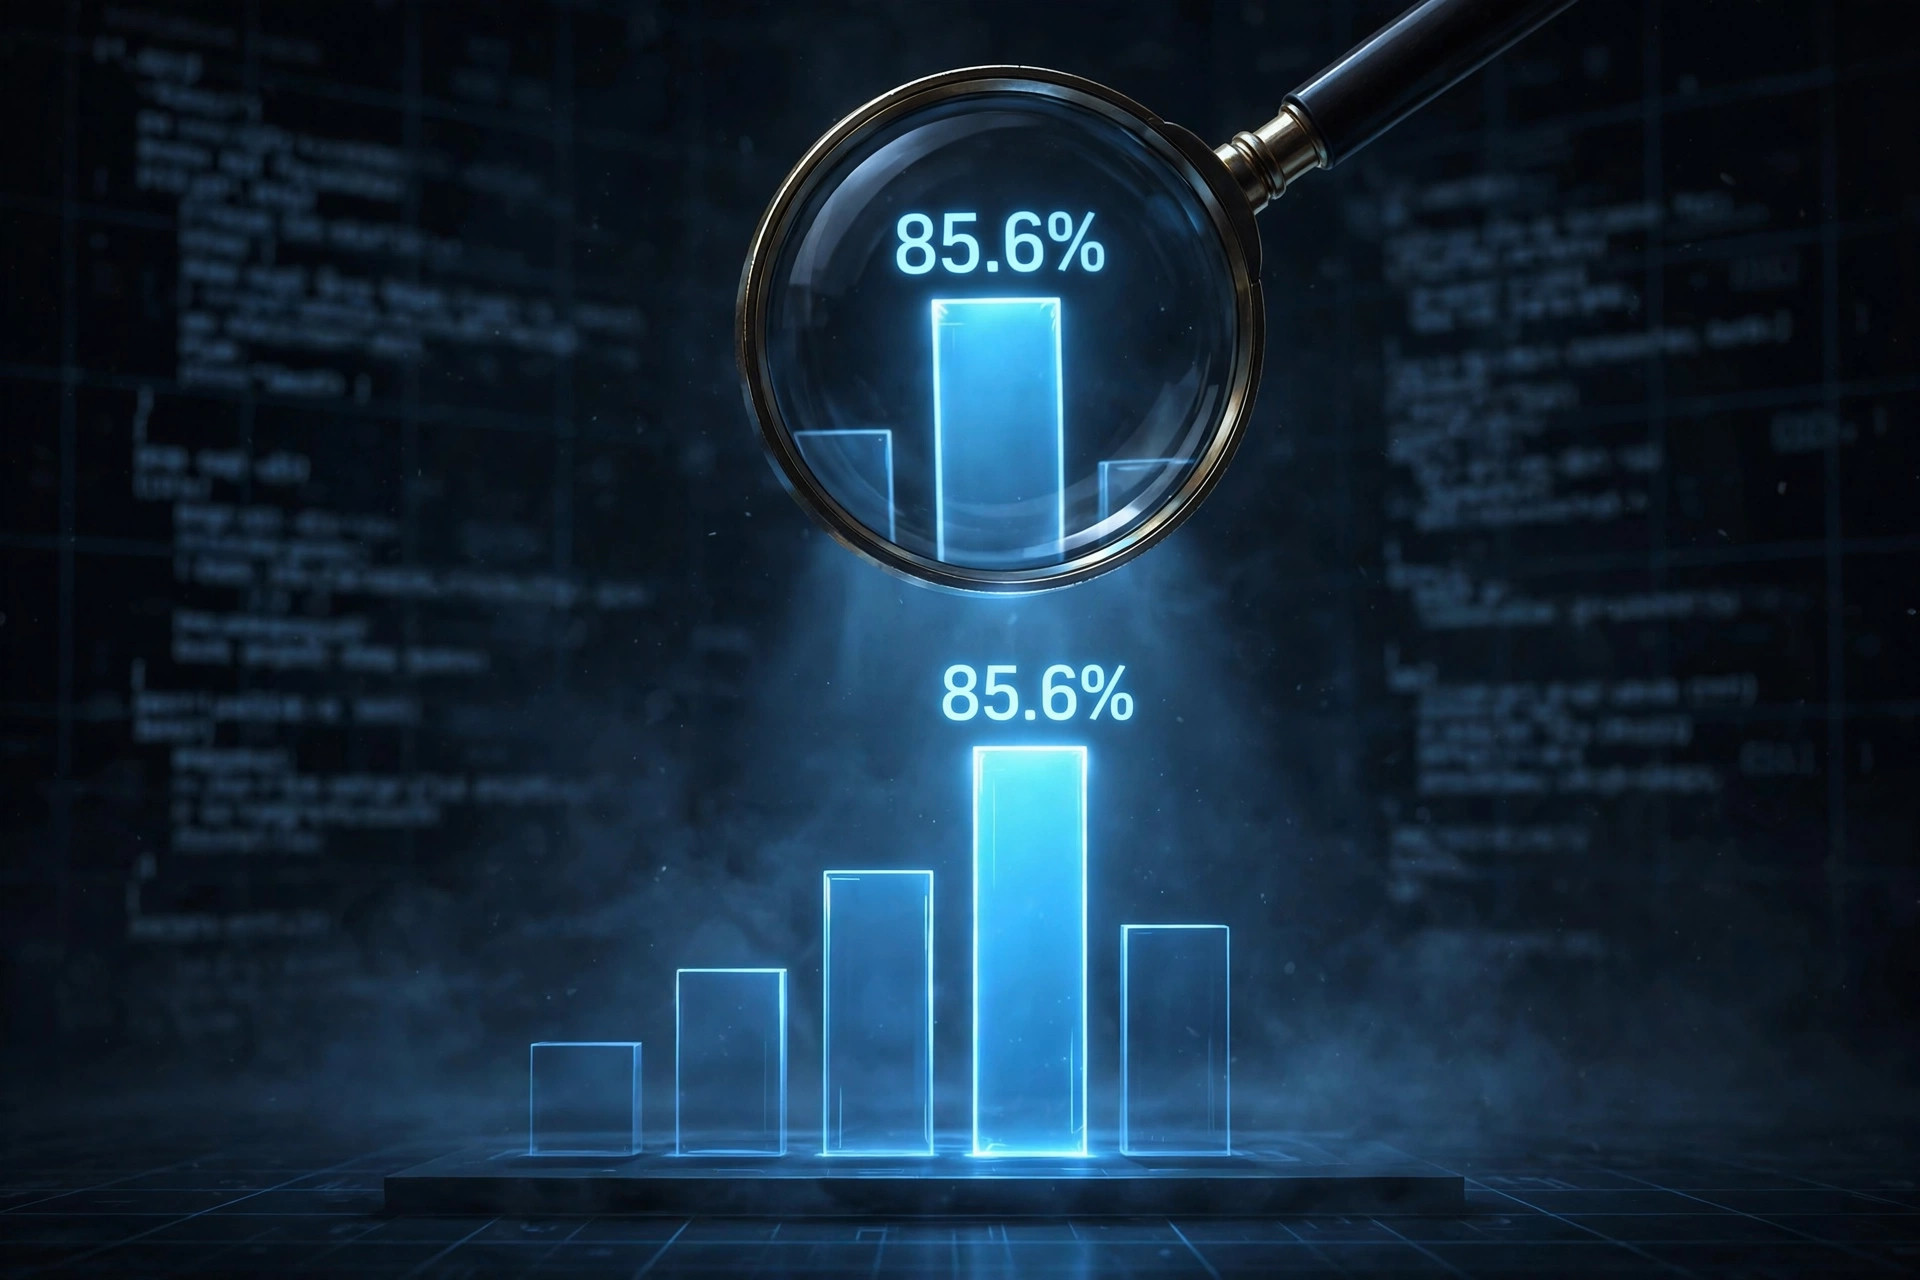
Meta says Muse Wonder leads on memory: the test is Meta's own, and it fits in one context window
Meta's Muse Wonder tops its own MemoryBench chart at 85.6. The card calls it an internal benchmark of recall in 64K to 100K token chats, and the window is 1M tokens. Our reading, untested: the test fits inside one context window.
A reranker gained 14 points on Hit@10. The answers barely moved.
A MedCPT cross-encoder lifted Hit@10 by 14 points on 1,000 clinical QA pairs, and answer correctness moved under 4. The authors' own words: retrieval gains do not translate proportionally into answer gains.
Can You Run a 1T Model on Your Own Iron?
Mistral's 1T-parameter 'Le Chonk' is Europe's biggest open-weight release ever. We did the hardware math: 1.05T params needs 2.1TB at FP16, about 1TB at FP8. Your 8xH100 box has 640GB.
Your router might be costing you more.
RouteLLM's paper promises 2x savings on single-turn benchmarks. We measured what happens in agent loops: switching models drops cache reads to zero, and the 1.25x write price gets paid again every turn.
dbt turned its AI on by default. Check the toggle.
From September 1, Wizard and Copilot ship enabled and every future dbt AI feature auto-enables. The meter is running, and the pool is shared.